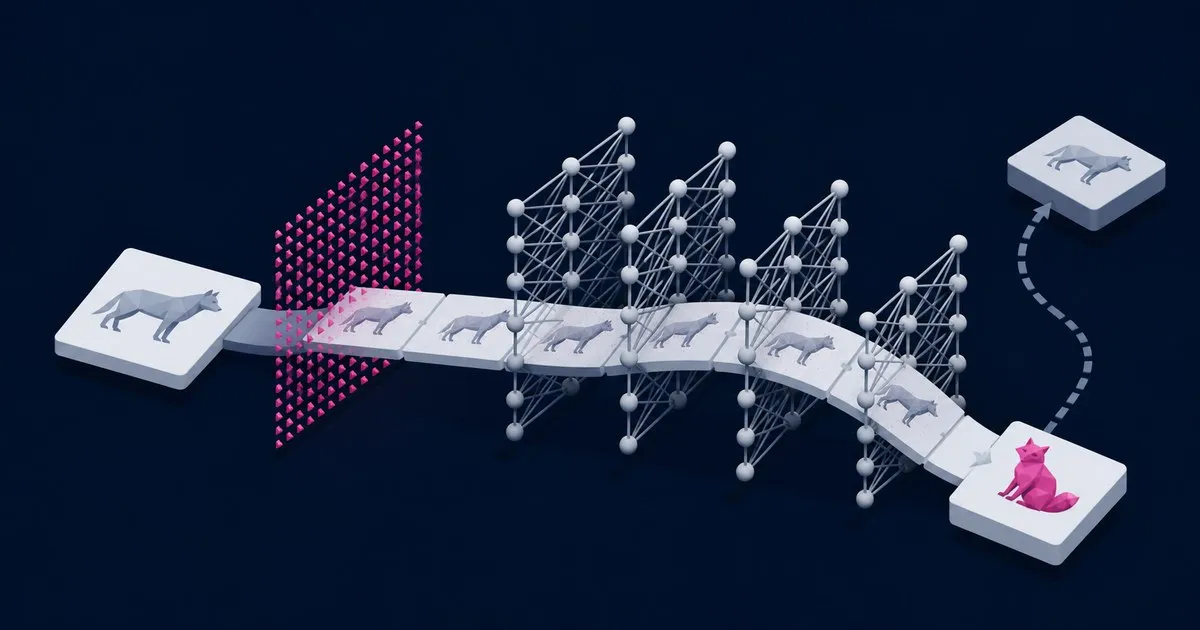
Understanding how FGSM adversarial attack works is the starting point for every robustness evaluation worth running. The Fast Gradient Sign Method, introduced by Ian Goodfellow, Jonathon Shlens, and Christian Szegedy in their 2014 paper “Explaining and Harnessing Adversarial Examples”, is the simplest white-box evasion attack in the adversarial ML literature: one forward pass, one backward pass, one pixel-wise nudge, and a classifier that was confident a moment ago now predicts the wrong class with equal confidence. It is not the strongest attack, but it is the canonical one, and any team claiming to evaluate model robustness without understanding it is measuring something they don’t fully control.
The Mechanics: One Gradient Step
During normal training a classifier minimizes a loss function J(θ, x, y) by adjusting the model parameters θ. FGSM runs the gradient computation in the opposite direction and adjusts the input instead.
The update rule is:
adv_x = x + ε · sign(∇_x J(θ, x, y))Breaking that down:
- x — the original input (e.g., a 224×224 RGB image)
- y — the correct label
- θ — model parameters, held fixed during the attack
- ∇_x J — gradient of the loss with respect to the input pixels, not the weights
- sign(·) — returns +1 or −1 for each element, discarding magnitude
- ε (epsilon) — a scalar that controls perturbation magnitude; typical values in image benchmarks are 0.01 to 0.3 on a [0,1]-normalized input
The sign function is the core design decision. Goodfellow et al. argued that neural networks’ vulnerability stems from their linear nature in high-dimensional spaces: even a tiny shift aligned with the gradient sign, applied independently to thousands of input dimensions, accumulates into a loss increase large enough to flip the prediction. Taking the sign instead of the raw gradient produces a uniform L∞-bounded perturbation — every pixel changes by exactly ε in the direction that hurts the model most. The resulting adversarial image looks identical to the original to a human observer but crosses a decision boundary.
In TensorFlow the attack reduces to four lines:
with tf.GradientTape() as tape:
    tape.watch(input_image)
    prediction = model(input_image)
    loss = loss_fn(true_label, prediction)

gradient = tape.gradient(loss, input_image)
perturbation = tf.sign(gradient)
adv_x = tf.clip_by_value(input_image + epsilon * perturbation, -1, 1)
The clip_by_value call enforces valid pixel range; the model parameters are never modified. This is a white-box attack: it requires access to the model’s gradients, which means either direct access to the model weights or a differentiable surrogate. See the TensorFlow FGSM tutorial for a complete runnable example against a pre-trained MobileNetV2 (ImageNet weights).
Epsilon trade-offs
Epsilon is a dial between attack success rate and perceptibility. At ε = 0, the output is the original image. As ε grows, misclassification rate climbs but the perturbation becomes visible — at ε = 0.3 on MNIST grayscale inputs the noise is obvious to any viewer. Choosing epsilon is an adversarial threat-model decision, not a hyperparameter tuning problem: it sets the L∞ budget the attacker is allowed, which should match the threat being modeled.
Why FGSM Still Appears in Every Benchmark
FGSM is weak against adversarially trained models. A single gradient step rarely clears the larger decision-boundary margins that adversarial training creates. Iterative extensions — most importantly Projected Gradient Descent (PGD), introduced by Madry et al. in 2018 — run the same gradient-sign step K times, projecting back into the L∞ ball after each step. PGD is strictly stronger than FGSM under the same epsilon budget and is the standard baseline for any claimed defense. The side-by-side comparison of the three canonical evasion attacks lives in Evasion Attacks on Image Classifiers: FGSM, PGD, and C&W.
Despite this, FGSM remains in circulation for three legitimate reasons:
1. Speed. A single gradient pass is cheap. When you need to generate adversarial augmentation at training time — Goodfellow et al.’s original adversarial training proposal mixes FGSM examples into the training batch — the per-example compute cost matters. FGSM adversarial training is fast enough to run during normal model training; PGD-AT increases compute by roughly K×.
2. Transferability baseline. Adversarial examples generated against one model often transfer to a different model trained on the same data. FGSM’s clean gradient computation produces examples where this cross-model transfer is well-studied. If you’re building a black-box attack using a surrogate model, FGSM on the surrogate is the first transferability probe to run.
3. Robustness evaluation floor. Any model that cannot withstand FGSM at small epsilon has a fundamental robustness problem. Defense papers that report only FGSM numbers are sandbagging — PGD and AutoAttack are the honest evaluation axes — but an FGSM number is still a sanity check. A model that fails FGSM at ε = 0.01 is not ready for adversarial evaluation.
ML platform teams monitoring deployed models should be collecting clean-to-adversarial accuracy gaps against FGSM as a lightweight early-warning metric; sentryml.com covers the observability infrastructure needed to do that continuously rather than as a one-shot audit.
Defending Against FGSM
No preprocessing trick robustly defeats FGSM across architectures and epsilon budgets. Defenses that appear to work often rely on obfuscated gradients — the attack’s gradient computation returns an uninformative signal because the defense breaks differentiability, not because the model is genuinely robust. The canonical way to verify this failure mode is to run a BPDA (backward pass differentiable approximation) or to fall back to a score-based black-box attack and compare success rates. The full checklist for spotting a robustness number that rests on masked gradients is in evaluating adversarial robustness correctly.
Practical defenses that hold up to scrutiny:
- PGD-AT — adversarial training using K-step PGD examples at the chosen epsilon budget. Madry et al.’s formulation is the empirical standard. It is expensive, it degrades clean accuracy, and it only provides robustness at the epsilon it was trained against, but it is the defense that has held up longest under adaptive attack evaluation. See adversarial training best practices for how the epsilon schedule and clean-accuracy trade-off are usually set.
- Randomized smoothing — adds Gaussian noise to the input and aggregates predictions across samples, providing certified L2 robustness guarantees. Incompatible with L∞-bounded FGSM guarantees but useful for image classification at scale.
- Input preprocessing with certified margins — denoising or feature squeezing as a pre-filter. Empirically useful at small epsilon; known to fail at larger budgets and against adaptive attackers who account for the preprocessing step, and a 2026 preprint reports that it fails on depthwise-separable edge CNNs.
- Gradient masking detection — run FGSM at escalating epsilon and compare accuracy degradation curves to an undefended model. Curves that are suspiciously flat at small epsilon often indicate masking rather than robustness.
For teams building guardrails around deployed vision or multimodal models, guardml.io writes about guardrails, content filters and model defenses for safe deployment.
The adversarial ML field has moved well past FGSM as an attack — C&W, PGD, AutoAttack, physical-world adversarial patches, and universal perturbations are the more operationally relevant threat classes now. But FGSM is where the math becomes legible, and the math is the foundation. Red-teamers who skip it to jump straight to AutoAttack often miss the structural insight that makes all gradient-based attacks work: you are not inverting the model, you are following its own loss surface to wherever it leads the input furthest from its correct prediction.
Related across the network
- Adversarial Examples Explained Simply: How Pixels Fool a Model — aiattacks.dev
- Evasion Attacks on Production Classifiers: Malware, Spam, Fraud — aiattacks.dev
- AI Security: Attack Categories, Defense Gaps, and How to Respond — ai-alert.org
- LLM Supply Chain Poisoning: Training Data Attacks and Backdoors — ai-alert.org
- Machine Learning Security: Threats, Frameworks, and Defenses — ai-alert.org


